Before a website lets someone create an account, post a comment, buy a ticket, or reset a password, it may ask for a small favor: click a box, identify traffic lights, type a few distorted characters, or solve a visual puzzle.
That interruption is a CAPTCHA, a computer security system designed to distinguish people from automated programs. Its name is an acronym for “Completely Automated Public Turing test to tell Computers and Humans Apart.” The phrase is awkward, but the problem it describes is enduring. The internet is full of useful forms and services, and software can fill those forms far faster than any person can.
A CAPTCHA is an attempt to keep automated abuse from overwhelming a digital doorway. It is also a compact history of the changing relationship between human judgment, machine vision, accessibility, and artificial intelligence.
A problem created by an open internet
Websites have always needed to know whether a request comes from a person or a program. Automated software is not inherently harmful. Search engines use bots to index pages, companies use scripts to process data, and accessibility tools rely on software to interpret websites.
The trouble begins when automation is used to create thousands of accounts, flood a discussion board with spam, submit repeated votes, scrape limited goods, or test stolen passwords against an online login form. A website may not be able to block every suspicious request by its internet address, because many legitimate people can share an address and attackers can distribute their traffic across many machines.
CAPTCHAs emerged as one answer: create a task that should be easy for a person but difficult for a computer program to complete reliably at scale.
Researchers at Carnegie Mellon University helped give the idea its modern form. Luis von Ahn, Manuel Blum, Nicholas Hopper, and John Langford described the approach in a 2003 paper, presenting CAPTCHAs as a way to use difficult artificial-intelligence problems for security. The key insight was unusual: a website could turn the gap between human and machine abilities into a defensive tool. For related reading, see Linux: How a Student’s Operating System Became the Internet’s Quiet Foundation.
Why distorted letters became so familiar
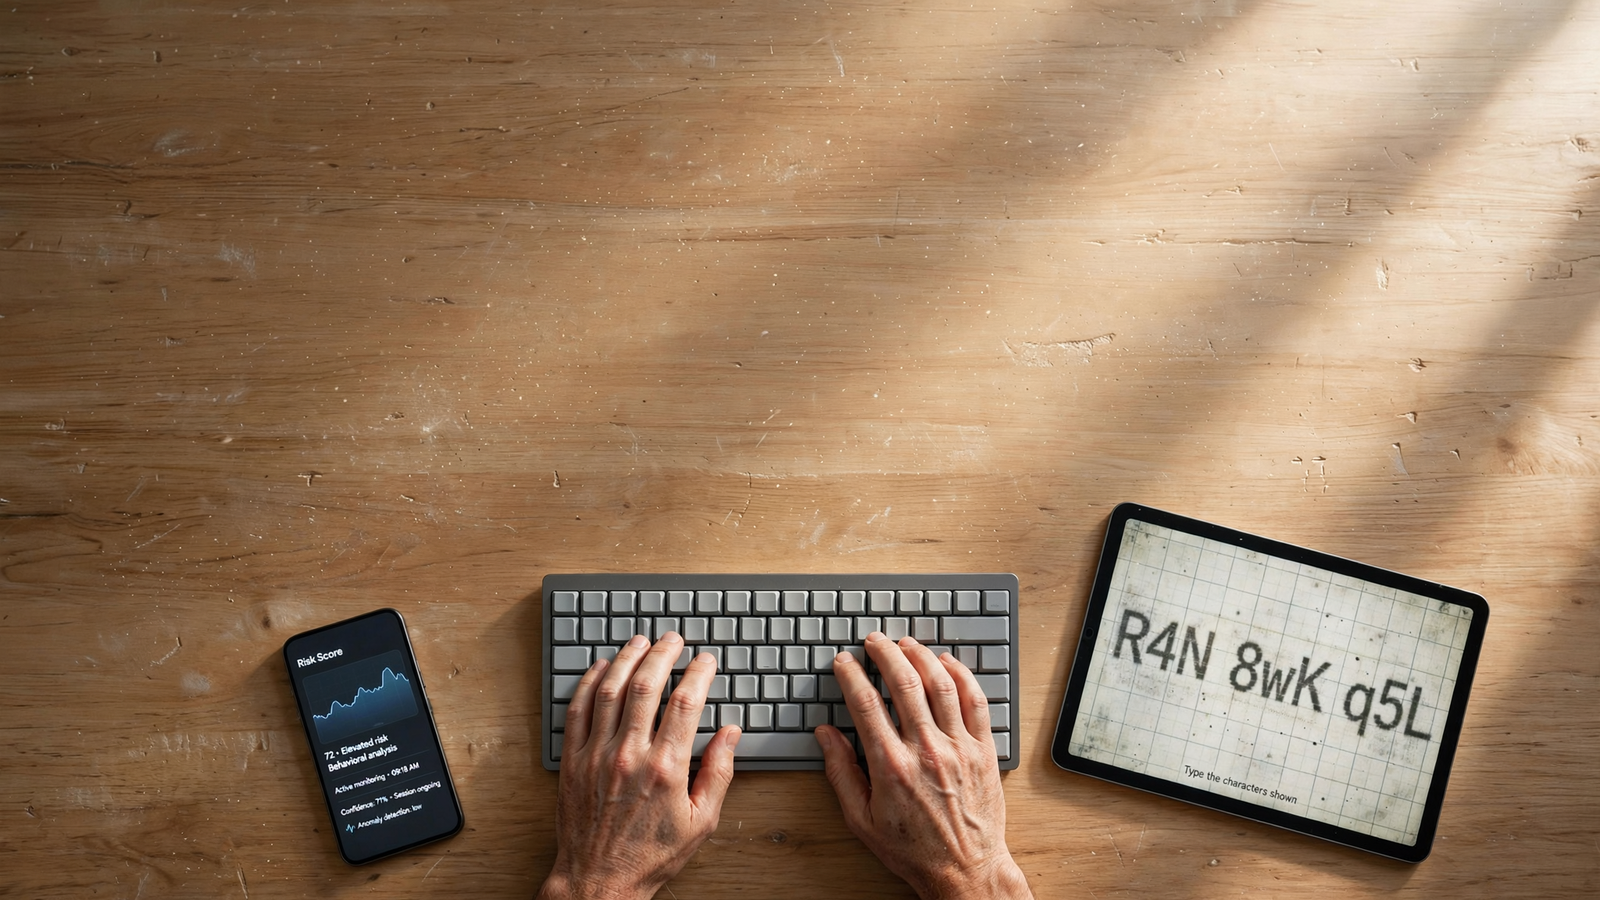
The classic CAPTCHA displayed a short word or sequence of characters with lines, bends, visual noise, and uneven spacing. A visitor typed what they saw. A computer program had to recognize the characters despite the interference.
For years, this seemed like a reasonable compromise. Humans are good at recognizing familiar shapes even when a picture is messy. Older computer-vision systems struggled with the same distortions, especially when the characters overlapped or changed size.
But a CAPTCHA was never a test of intelligence in a broad sense. It tested performance on one carefully selected task under particular conditions. A person who could not see the image, could not use a mouse, had dyslexia, or was working through a slow connection might find the test harder than a bot. Meanwhile, a specialized program could improve as researchers learned more about the visual patterns.
That tension explains why CAPTCHA design has never settled into one permanent format. Once a challenge becomes predictable, attackers can train software for it. Once it becomes more complicated, legitimate users may pay the price.
When security became a tool for preserving books
One of the most inventive developments came from reCAPTCHA, a project associated with von Ahn and his colleagues. Instead of asking users to solve meaningless puzzles, early reCAPTCHA challenges used words taken from scanned books and newspapers that optical character-recognition software could not confidently read.
The system presented two words. One was a known answer used to check the visitor’s response. The other came from a difficult scan. If enough people independently supplied the same answer for the unknown word, the system could treat that consensus as evidence of what the scan said.
In this way, a short security check also contributed to the conversion of printed material into searchable digital text. A visitor was not consciously volunteering to be a library assistant; they were simply trying to continue through a web form. Yet the aggregate result could help recover words that machines had missed.
Google acquired reCAPTCHA in 2009. The company said the technology could help digitize books, newspapers, and old radio programs while protecting websites from automated abuse. The arrangement illustrated an important characteristic of internet infrastructure: a routine action performed by millions of people can become useful data when it is carefully organized. For related reading, see Reinforcement Learning: How Trial and Error Became a Core Idea in AI.
From visible puzzles to invisible judgments
CAPTCHA systems gradually moved beyond distorted text. Some asked users to select every image containing a bus, bicycle, storefront, or traffic light. Others used an audio challenge for people who could not use the visual version. Later systems tried to judge risk without presenting a puzzle at all.
Google’s reCAPTCHA v3, introduced in 2018, describes itself as a system that returns a score representing how suspicious an interaction appears. Rather than interrupting every visitor, it allows a website to decide what action to take when the score is low. A site might request additional verification, limit an action, or allow the visitor through.
This approach reflects a basic change in security thinking. A single puzzle asks, “Can this visitor solve this task?” A risk-based system asks a broader question: “Does this interaction resemble ordinary human use of this website?”
That decision can draw on signals such as the timing and sequence of actions, the page being visited, and other information available to the site. The exact signals and thresholds vary, and a score is not a declaration that someone is or is not human. It is a risk estimate.
The cost of proving you are a person
CAPTCHAs are useful, but they are not neutral. A visual test can be difficult or impossible for blind and low-vision users. Audio alternatives may be hard to understand because of background noise or distorted speech. People with motor disabilities may struggle with time limits, small controls, or repeated clicking.
Language, culture, device size, internet speed, and unfamiliar image categories can also affect performance. A person using a phone in bright sunlight may have a different experience from someone sitting at a large desktop monitor. A visitor who fails several times may not know whether the problem was a wrong answer, a network error, or a security system that quietly rejected the interaction.
Accessibility specialists have therefore long warned that a CAPTCHA should not be treated as a complete accessibility strategy. The World Wide Web Consortium has documented the barriers created by CAPTCHA and encouraged developers to provide alternatives and consider whether a challenge is necessary at all. For related reading, see The Little Free Pantry: How a Box by the Sidewalk Became a Neighborhood Habit of Care.
There is also a privacy question. Invisible risk systems can be less frustrating than puzzles, but they may evaluate behavioral information that users do not see or understand. Removing a visible challenge does not necessarily remove the underlying observation.
Why the CAPTCHA keeps changing
The contest between CAPTCHAs and automated programs is not a one-time race with a final winner. It is an arms race shaped by economics. If a challenge protects an attractive target, someone has an incentive to solve, outsource, imitate, or bypass it.
Machine-learning systems have become much better at recognizing text and images, weakening the assumption that a visual puzzle is automatically harder for software than for people. Attackers may also avoid solving a challenge directly. They can abuse poorly protected application interfaces, take over legitimate accounts, use human-solving services, or make automated traffic resemble normal browsing.
For that reason, responsible website security usually treats CAPTCHA as one layer rather than a complete defense. Rate limits, device and account monitoring, password protections, multifactor authentication, fraud detection, and careful form design can all matter. The best choice depends on what a service is protecting and what risks it can tolerate.
A small window into computer security
The CAPTCHA remains interesting because it turns an abstract security problem into a moment of everyday interaction. It reminds us that computers do not simply divide the world into human and machine. They measure patterns, assign probabilities, and make decisions under uncertainty.
It also reveals that “easy for a person” is not the same as “easy for every person.” A system designed around an imagined average user can quietly exclude real users, while a system designed to be friendlier may give attackers more room to operate.
The future of CAPTCHA may involve fewer puzzles and more behind-the-scenes checks, but the underlying question will remain: how can an open digital service welcome legitimate people without making itself effortless for abuse? Every time a website asks a visitor to click, type, or wait, it is negotiating that question in miniature.
Use: Primary research paper by Luis von Ahn, Manuel Blum, Nicholas Hopper, and John Langford explaining the CAPTCHA concept and its security rationale.
Use: Background on reCAPTCHA’s use of difficult scanned words and Google’s acquisition of the project.
Use: Current developer documentation describing reCAPTCHA v3’s score-based, risk-analysis approach.
Use: Accessibility context on why CAPTCHA challenges can create barriers and why alternatives matter.
Carnegie Mellon University — CAPTCHA: Using Hard AI Problems for Security — https://www.cs.cmu.edu/~biglou/captcha.pdf — Primary research paper by Luis von Ahn, Manuel Blum, Nicholas Hopper, and John Langford explaining the CAPTCHA concept and its security rationale.
Google Research Blog — reCAPTCHA: Improving Text on the Web — https://googleblog.blogspot.com/2009/09/recaptcha-improving-text-on-web.html — Background on reCAPTCHA’s use of difficult scanned words and Google’s acquisition of the project.
Google Developers — reCAPTCHA v3 — https://developers.google.com/recaptcha/docs/v3 — Current developer documentation describing reCAPTCHA v3’s score-based, risk-analysis approach.
World Wide Web Consortium — Inaccessibility of CAPTCHA — https://www.w3.org/WAI/GL/2005/06/overlapping-techniques.html — Accessibility context on why CAPTCHA challenges can create barriers and why alternatives matter.